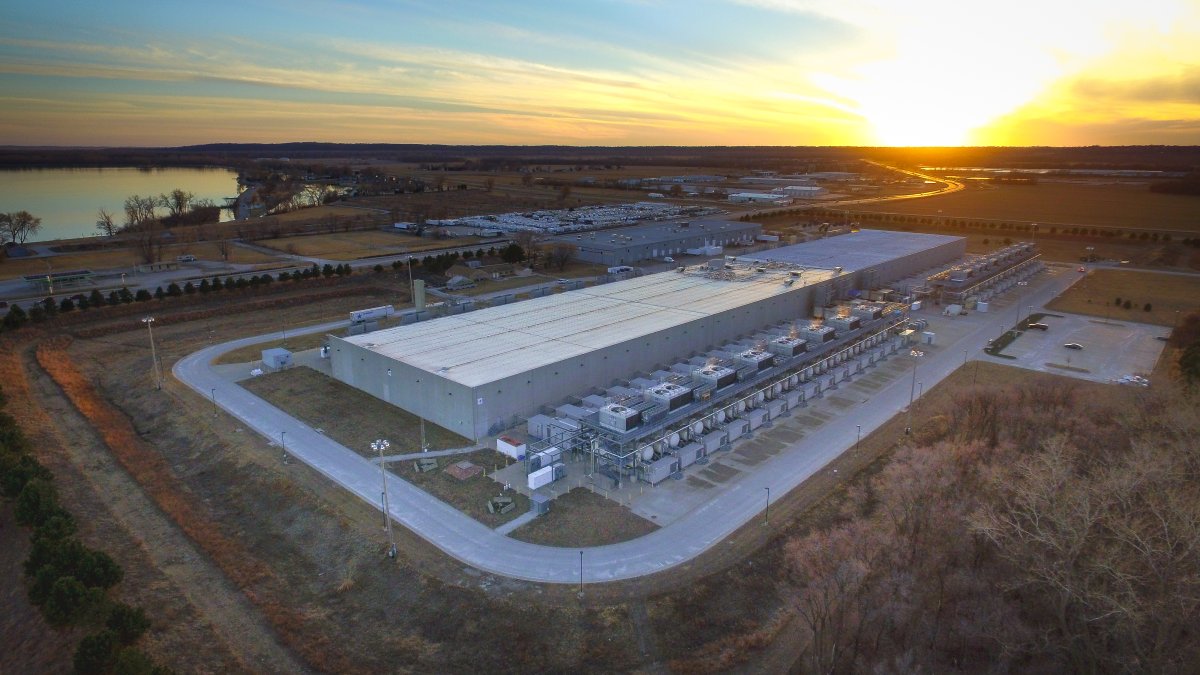
Google Cloud and NVIDIA used the GTC Berlin stage to detail the deepest infrastructure integration between the two companies yet. A5X, Google Clouds new bare-metal GPU instances built on the NVIDIA Vera Rubin NVL72 platform, will hit general availability next month, and the accompanying network blueprint outlines something larger: a fabric designed to scale from 80,000 Rubin GPUs within one site to as many as 960,000 GPUs across multi-site deployments. Both companies stress the figure is a planning ceiling, not metal in racks today, with actual buildout hostage to power, facilities and supply chain realities.
The instance itself is a dense package. Each A5X rack integrates Vera Rubin NVL72 systems of 72 GPUs and 36 Vera CPUs, NVIDIA ConnectX-9 SuperNICs, fourth-generation liquid cooling and Google Clouds new Virgo network, a mesh-topology fabric that supports non-blocking scale-out both inside a building and across buildings. Google says Virgo is what lets clusters expand horizontally without the usual bottlenecks, a direct answer to the multi-site training and reinforcement learning workloads that frontier labs now demand.
Storage and memory got the same treatment. A5X instances will support Managed Lustre with NVIDIA GPUDirect Storage, giving training data a direct RDMA path from the parallel file system into GPU memory, and advanced KV caching designed to stretch context memory beyond GPU HBM for long-context and multi-turn agentic workloads. Google claims the caching layer reduces redundant computation and improves inference goodput per dollar. On the orchestration side, the instances slot into Google Kubernetes Engine with Managed DRANET and topology-aware Kueue scheduling.
The sovereignty angle matters as much as the silicon. Google Cloud is positioning A5X for European data residency requirements with new regional availability, becoming one of the first providers to offer rack-scale NVIDIA confidential computing on bare-metal instances, and extending confidential computing to G4 virtual machines built on RTX PRO 6000 Blackwell GPUs. Its Sovereign Cloud portfolio will also host open-weight models including Gemma, Mistral and NVIDIA Nemotron, letting regulated customers keep custody of weights and runtimes.
The first named customer is telling: Ineffable Intelligence, the London lab founded by DeepMind veteran David Silver, is already using A5X for large-scale reinforcement learning research. The choice of an RL-focused startup as launch customer underscores who this hardware is for, enterprises running continuous agentic and learning workloads rather than one-shot training bursts.
Timing is everything in this announcement. It lands days after OpenAI confirmed its frontier models and Codex workflows are coming to Google Cloud, making Google the only major cloud simultaneously selling GPT, Gemini and Claude. Google Cloud is now both a neutral model marketplace and the operator of one of the largest planned Rubin fleets on the planet, a combination that will pressure every hyperscaler negotiating GPU supply for 2027. The 960,000-GPU ceiling may be aspirational, but in a market where a three-month deployment delay on a gigawatt campus is measured in billions, publishing the ceiling is itself a competitive move.
Comments (0)
Log in to join the discussion
Log InNo comments yet